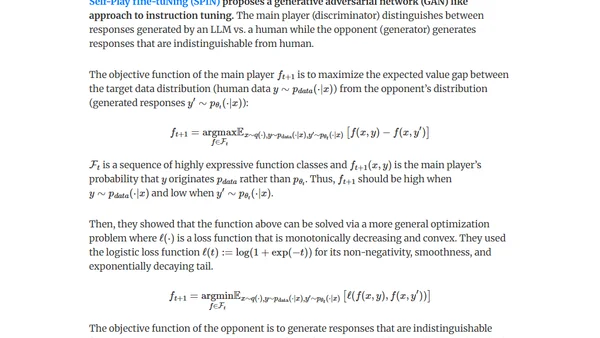
How to Generate and Use Synthetic Data for Finetuning
Explores methods for generating synthetic data (distillation & self-improvement) to fine-tune LLMs for pretraining, instruction-tuning, and preference-tuning.
A guide on running a Large Language Model (LLM) locally using Ollama for privacy and offline use, covering setup and performance tips.
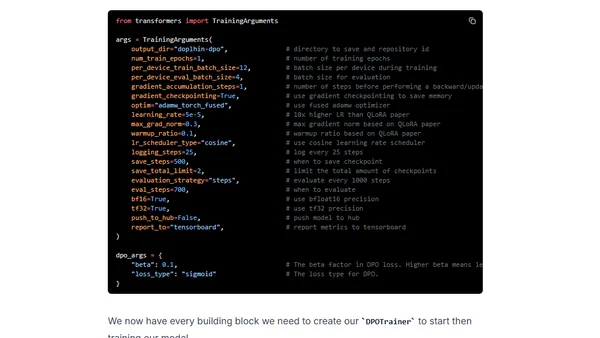
A technical guide on using Direct Preference Optimization (DPO) with Hugging Face's TRL library to align and improve open-source large language models in 2024.
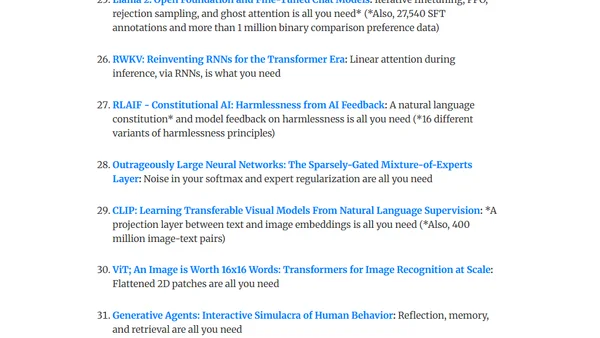
A curated reading list of fundamental language modeling papers with summaries, designed to help start a weekly paper club for learning and discussion.
Investigates why ChatGPT 3.5 API sometimes refuses to summarize arXiv papers, exploring prompts, content, and model behavior.
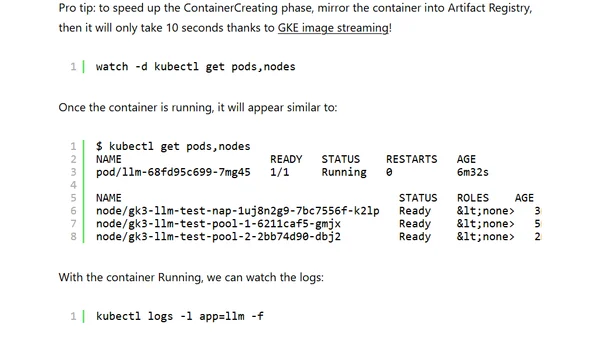
A guide to deploying and running your own LLM on Google Kubernetes Engine (GKE) Autopilot for control, privacy, and cost management.
A simple explanation of Retrieval-Augmented Generation (RAG), covering its core components: LLMs, context, and vector databases.
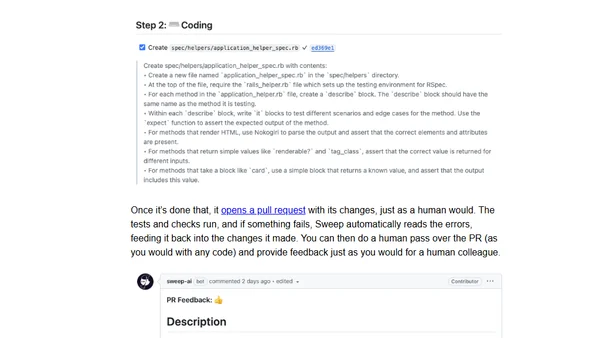
A developer's experience using Sweep, an LLM-powered tool that generates pull requests to write unit tests and fix code in a GitHub workflow.
An analysis of ChatGPT's knowledge cutoff date, testing its accuracy on celebrity death dates to understand the limits of its training data.
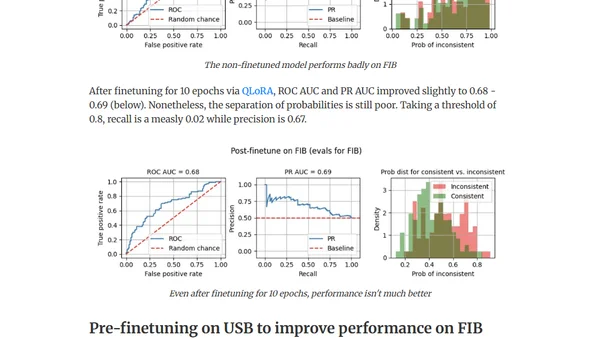
Explores using out-of-domain data to improve LLM finetuning for detecting factual inconsistencies (hallucinations) in text summaries.
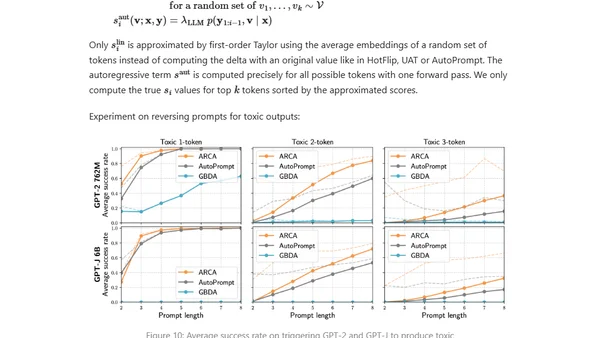
Explores adversarial attacks and jailbreak prompts that can make large language models produce unsafe or undesired outputs, bypassing safety measures.
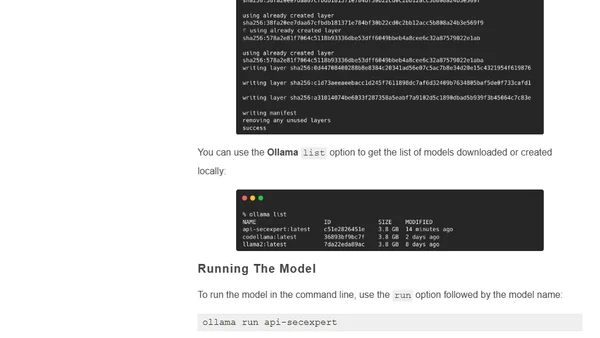
A guide on using Ollama's Modelfile to create and deploy a custom large language model (LLM) for specific tasks, like an API security assistant.
Key takeaways from the AI Engineer Summit 2023, focusing on challenges in LLM deployment like evaluation methods and serving costs.
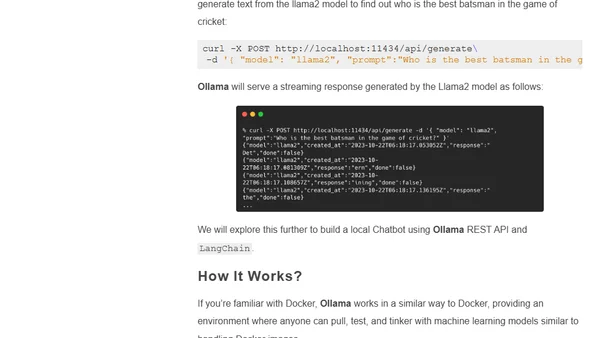
A guide to using Ollama, an open-source CLI tool for running and customizing large language models like Llama 2 locally on your own machine.
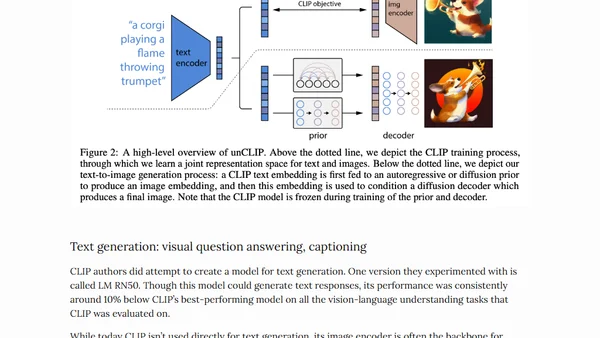
An in-depth exploration of Large Multimodal Models (LMMs), covering their fundamentals, key architectures like CLIP and Flamingo, and current research directions.
A summary of a keynote talk on essential building blocks for production LLM systems, covering evaluations, RAG, and guardrails.
A developer's weekly learning log covering Azure Machine Learning, Prompt Flow, Microsoft Fabric, Copilot, and an LLM hallucination paper.
Explains why traditional debugging fails for LLMs and advocates for observability-driven development to manage their non-deterministic nature in production.
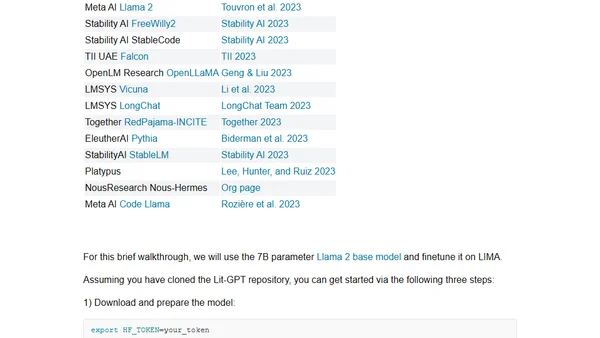
Strategies for improving LLM performance through dataset-centric fine-tuning, focusing on instruction datasets rather than model architecture changes.
Explores dataset-centric strategies for fine-tuning LLMs, focusing on instruction datasets to improve model performance without altering architecture.