Refactoring English: Month 21
« PreviousOne-Line SummaryMaybe I’ll print physical books after allNew here?Hi, I’m Michael. I’m a software developer and founder of small, indie tech
TL;DR Different workload service classes need different capacity, data services, lifecycle practices, and recovery controls. A private cloud operating
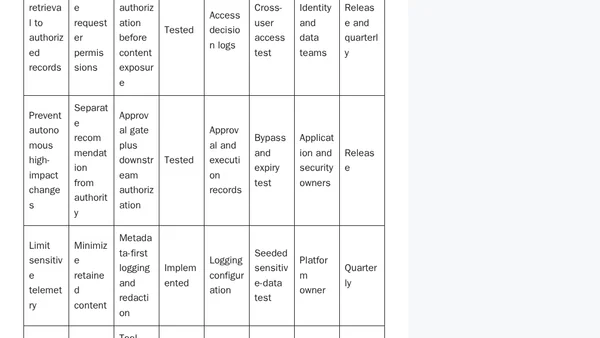
TL;DR AI agent authorization must connect permission to the exact action, executing identity, target, current policy, and validity window. A verified
What's been going on in w64devkit the past year September 20, 2026 nullprogram.com/blog/2026/09/20/ The past year has been exciting for w64devkit, whi
TL;DR The Enterprise Universal Prompt Optimizer, version 1.0, defines a vendor-neutral method for turning a rough request into a self-contained AI pro
TL;DR Most executive decision briefs fail before the recommendation is written. The problem is usually not a lack of information. It is that the decis
TL;DR Enterprise research fails when AI is treated as a faster search engine instead of a controlled evidence system. A polished answer with twenty ci
TL;DR Enterprise document synthesis is not primarily a summarization problem. It is an evidence-preservation problem. The AI must retain the differenc
TL;DR Enterprise data analysis fails surprisingly often before the first formula is calculated. The business question is vague, the unit of analysis i
TL;DR AI can accelerate enterprise architecture work, but speed is not the same thing as architectural quality. A model can produce a convincing diagr
TL;DR AI can generate a plausible API, script, integration, data pipeline, or infrastructure automation surprisingly quickly. That does not mean the w
TL;DR Enterprise security, privacy, governance, and compliance assessments should produce a defensible risk decision, not a collection of questionnair
TL;DR Enterprise AI use case evaluation should begin with a measurable workflow problem, not a request for a model, copilot, or agent. Before selectin
TL;DR Adding a second or third AI reviewer can improve coverage, expose disagreements, and reduce some individual model errors. It does not automatica
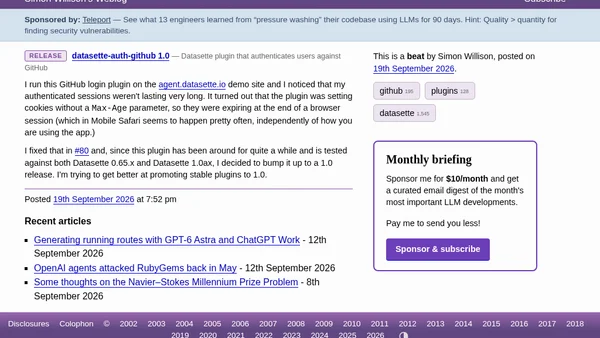
19th September 2026 Release datasette-auth-github 1.0 — Datasette plugin that authenticates users against GitHub I run this GitHub login plugin on the
TL;DR AI agent execution gate testing should establish whether a prohibited action remains blocked when the reviewer gets the decision wrong. Submit t
TL;DR Start a Recursive Trust Benchmark pilot by proving the measurement path before comparing reviewers. Validate the source cases, keep the answer k
TL;DR The Recursive Trust Benchmark is a proposed method for comparing whether different assurance designs detect incorrect proposals, prevent prohibi
Simon Willison’s Weblog Subscribe Sponsored by: Teleport — See what 13 engineers learned from “pressure washing” their codebase using LLMs for 90 days
TL;DR AI agent disaster recovery must address the possibility that the model, memory, policy, evaluator, or evidence is unreliable even while the infr