Behaviorism and AI: How Rewards Shape Model Behavior
Explores how behaviorism and reinforcement learning shape AI behavior, and why rewards don't guarantee intended outcomes in enterprise AI systems.
Analyzes the use of reinforcement learning to enhance reasoning capabilities in large language models (LLMs) like GPT-4.5 and o3.
Explores reward hacking in reinforcement learning, where AI agents exploit reward function flaws, and its critical impact on RLHF and language model alignment.
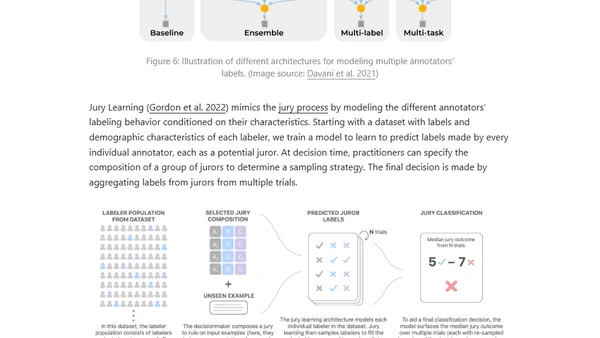
Explores the importance of high-quality human-annotated data for training AI models, covering task design, rater selection, and the wisdom of the crowd.
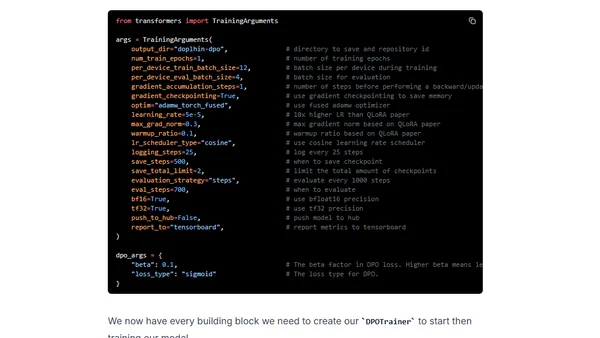
A technical guide on using Direct Preference Optimization (DPO) with Hugging Face's TRL library to align and improve open-source large language models in 2024.