Local Open-Weight LLMs in Coding Harnesses
Testing local open-weight LLMs like Qwen-Code and Codex in coding harnesses, comparing token use and task success.
SebastianRaschka.com is the personal blog of Sebastian Raschka, PhD, an LLM research engineer whose work bridges academia and industry in AI and machine learning. On his blog and notes section he publishes deep, well-documented articles on topics such as LLMs (large language models), reasoning models, machine learning in Python, neural networks, data science workflows, and deep learning architecture. Recent posts explore advanced themes like “reasoning LLMs”, comparisons of modern open-weight transformer architectures, and guides for building, training, or analyzing neural networks and model internals.
142 articles from this blog
Testing local open-weight LLMs like Qwen-Code and Codex in coding harnesses, comparing token use and task success.
Analysis of GLM-5.2, a new open-weight model with IndexShare for efficient long-context sparse attention.
Analysis of VibeThinker-3B, a small AI model achieving strong coding and reasoning performance through advanced post-training techniques.
Analysis of Cohere's new North Mini Code model for agentic coding tasks, including architecture and benchmark performance.
A curated list of LLM research papers from January to May 2026, covering architecture, reasoning, RL, agents, and more.
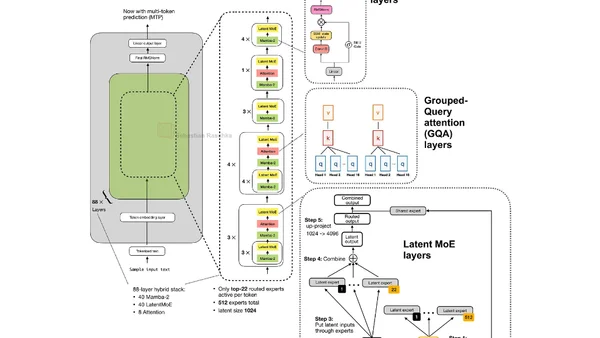
Analysis of Nemotron 3 Ultra, a 550B parameter LLM using Latent MoE scaling and hybrid Mamba-Transformer architecture.
Analysis of MiniMax M2 LLM technical report: sparse MoE, full attention, agent training, and production-oriented model design.
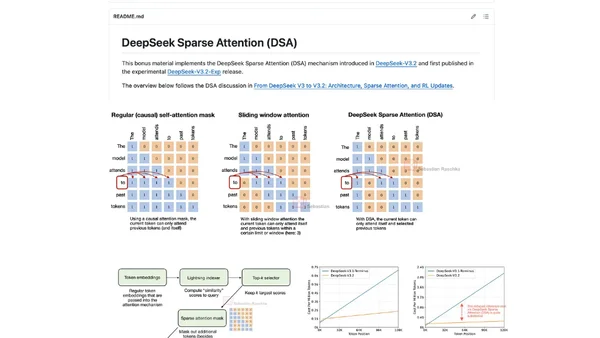
DeepSeek Sparse Attention implementation from scratch, featuring a learned sparse pattern replacing fixed attention with a lightweight indexer and selector.
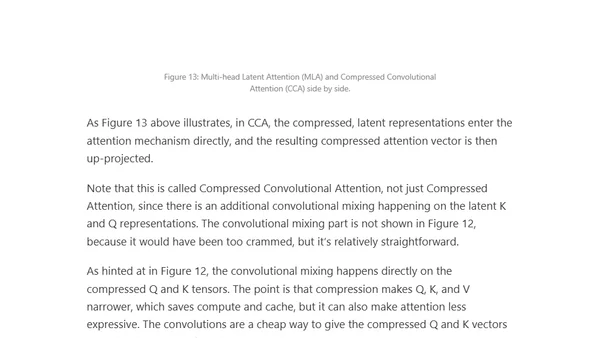
Analysis of recent LLM architecture innovations including KV sharing, compressed attention, and mHC for reducing long-context costs.
A talk on implementing LLM architectures from scratch in Python and PyTorch, covering workflow for analyzing new models.
A workflow for understanding open-weight LLM architectures using config files and code from Hugging Face.
An overview of coding agent components, including tools, memory, and repo context, and how they enhance LLM performance in practice.
Analysis of Gemma 4 architecture, benchmarks, and licensing compared to Gemma 3 and other models.
New LLM Architecture Gallery diff tool lets you compare model architecture stacks side by side, highlighting key differences.
A visual guide to attention variants in modern LLMs, covering MHA, GQA, MLA, sparse attention, and hybrid architectures.
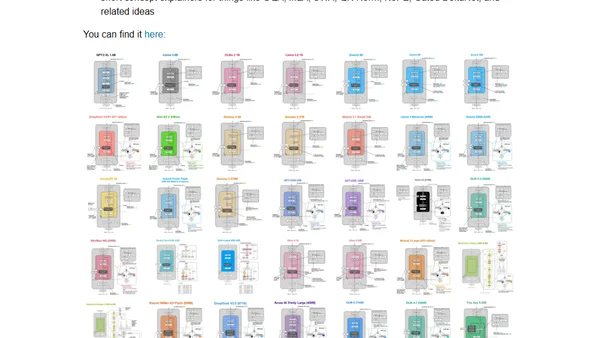
A gallery showcasing and comparing architecture diagrams and technical details of recent open-weight Large Language Models (LLMs).
Analysis of NVIDIA's Nemotron 3 Super 120B-A12B model focusing on its accuracy-throughput trade-off design and efficiency features.
A 4.5-hour interview discussing the state of AI in 2026, covering LLMs, geopolitics, training, open vs. closed models, AGI timelines, and industry implications.
An overview of inference-time scaling methods for improving LLM reasoning, categorizing techniques and highlighting recent research.
A 2025 year-in-review analysis of large language models (LLMs), covering key developments in reasoning, architecture, costs, and predictions for 2026.