What Is Data Modeling? A Complete Guide
A comprehensive guide to data modeling, explaining its meaning, three abstraction levels, techniques, and importance for modern data systems.
Explains the three levels of data modeling (conceptual, logical, physical) and their importance in database design.
Compares Star Schema and Snowflake Schema data models, explaining their structures, trade-offs, and when to use each for optimal data warehousing.
Explores how data modeling principles adapt for modern lakehouse architectures using open formats like Apache Iceberg and the Medallion pattern.
Explains dimensional modeling for analytics, covering facts, dimensions, grains, and table design for query performance.
Explains Slowly Changing Dimensions (SCD) types 1-3 for managing data history in data warehouses, with practical examples.
Explains why transactional data models are inefficient for analytics and how to design denormalized, query-optimized models for better performance.
Explains database denormalization: when to flatten data for faster analytics queries and when to avoid it.
Explains Data Vault data modeling, its core components (Hubs, Links, Satellites), and the problems it solves for complex, evolving data sources.
Seven common data modeling mistakes that cause reporting errors and slow analytics, with practical solutions to avoid them.
Explains what a semantic layer is, its components, and how it provides consistent business definitions for data queries and AI agents.
A step-by-step guide to building a robust semantic layer for consistent data metrics, covering architecture, stakeholder alignment, and implementation.
Explains the difference between a metrics layer and a semantic layer in data architecture, clarifying their distinct roles and relationship.
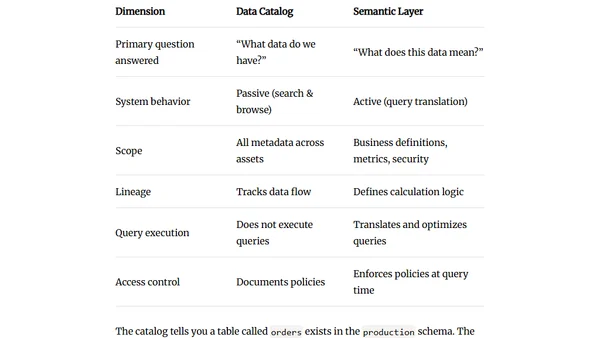
Explains the distinct roles of data catalogs and semantic layers in data architecture, arguing they are complementary tools.
Explains why AI data analytics fail without a semantic layer to define business metrics and ensure accurate, secure queries.
Explains how a semantic layer enforces data governance by embedding policies directly into the query path, ensuring consistent metrics and access control.
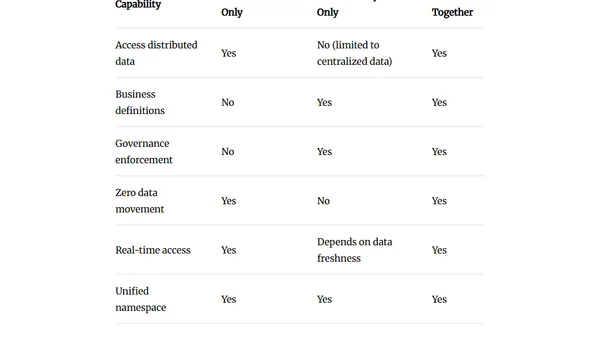
Explains how data virtualization and a semantic layer enable querying distributed data without copying, reducing costs and improving freshness.
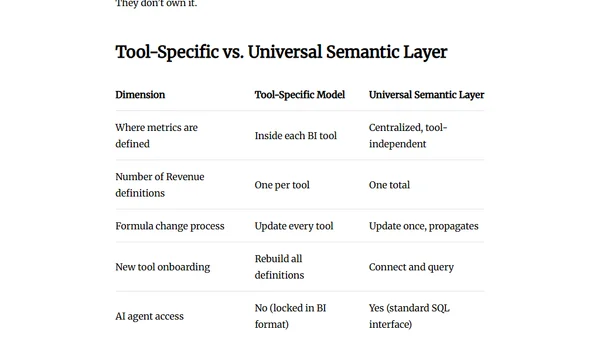
Explains Headless BI and how a universal semantic layer centralizes metric definitions to replace tool-specific models, enabling consistent analytics.
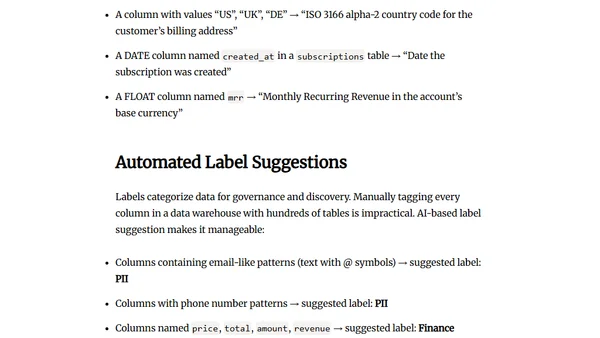
Explains how a self-documenting semantic layer uses AI to automate data documentation, reducing manual work and governance risks for data teams.
Seven critical mistakes that can derail semantic layer projects in data engineering, with practical advice on how to avoid them.