What is an LLMs.txt File?
Explains the LLMs.txt file, a new standard for providing context and metadata to Large Language Models to improve accuracy and reduce hallucinations.
A guide to using browser-use, a scriptable AI agent built with Playwright and LLMs to automate repetitive browser tasks.
Explores using Bing Search API to ground LLM responses for website assistants, comparing custom implementation with Azure AI Agent Service.
A technical tutorial demonstrating mouse right-click operations and stream()/has-text() methods using Playwright Java for test automation.
A technical tutorial on creating interactive data tables by web-scraping with R's rvest package and styling with reactable.
Analysis of 5 years of Hacker News 'Who's Hiring' thread data using Deno and the HN API to visualize tech hiring trends.
Cloudflare now offers a simple setting to block AI bots from scraping your website, available even on free plans.
Argues for an evolved robots.txt standard with AI-specific rules and regulations to enforce them, citing Perplexity AI's violations.
A guide to installing and configuring Playwright for browser automation on Heroku using Node.js, including dependency management and code structure.
A developer details the process of scraping a restaurant week website's API to create a better UI, covering reverse-engineering and data presentation.
How to automatically check internal links on a static site using Scrapy and GitHub Actions for continuous integration.
A developer shares technical challenges and solutions for building reliable web scraping features for a SaaS website monitoring tool.
A technical analysis of UK rainfall data, covering data scraping, visualization, and processing using Python and APIs.
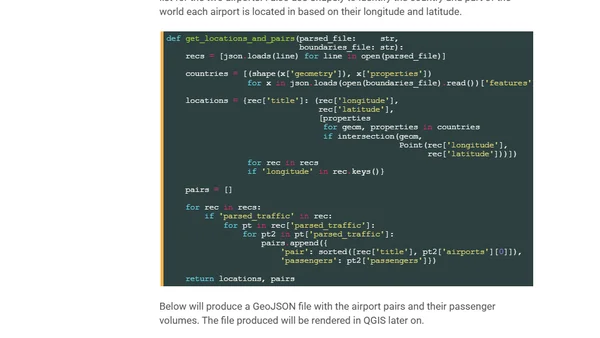
A technical walkthrough of scraping and visualizing global airline passenger route data using Python, DuckDB, and QGIS.
Advanced techniques for customizing element screenshots in Playwright, including DOM manipulation and image preprocessing.
A technical tutorial on web scraping and text analysis using R and ggplot2 to analyze descriptions of US Wilderness Areas.
A programmer's guide to automating a badminton court booking system using Selenium and Python to secure time slots.
A guide to using GitHub Actions to monitor API responses or web pages for changes and receive automated notifications via SMS or other channels.
A technical tutorial on using R and the rvest package to scrape data from multiple web pages, including handling pagination.
Explores user-built alternatives like Nitter and Invidious that reclaim the web from corporate platforms by offering ad-free, privacy-focused interfaces.