Muse Glimmer 30B Architecture Notes
Analysis of Meta's new open-weight Muse Glimmer 30B LLM, focusing on its architecture, KV-cache efficiency, and comparison to similar models.
Explores recent LLM architecture innovations like KV sharing, compressed attention, and mHC for long-context efficiency.
Analysis of recent LLM architecture innovations including KV sharing, compressed attention, and mHC for reducing long-context costs.
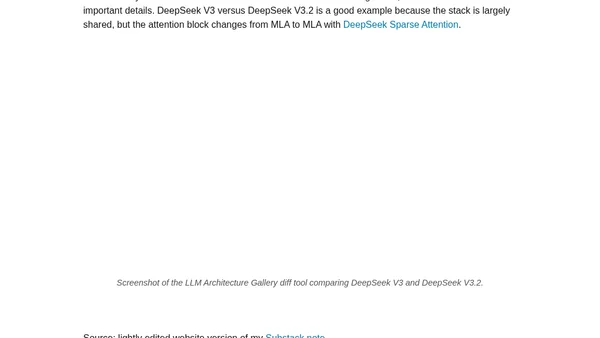
New LLM Architecture Gallery diff tool lets you compare two models side-by-side, highlighting key architectural differences.
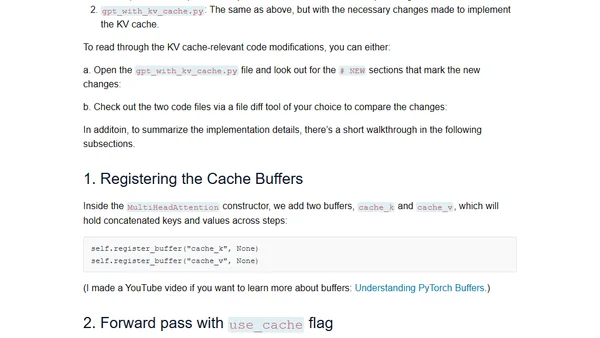
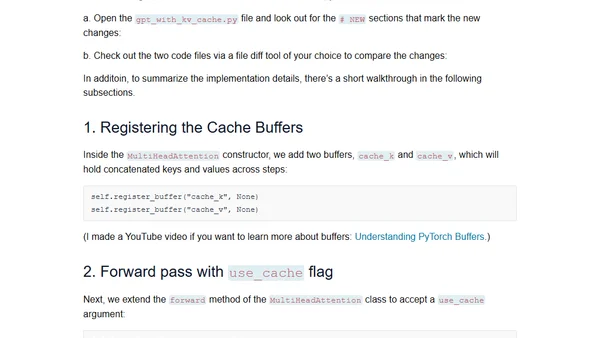
Explains the KV cache technique for efficient LLM inference with a from-scratch code implementation.
A technical tutorial explaining the concept and implementation of KV caches for efficient inference in Large Language Models (LLMs).
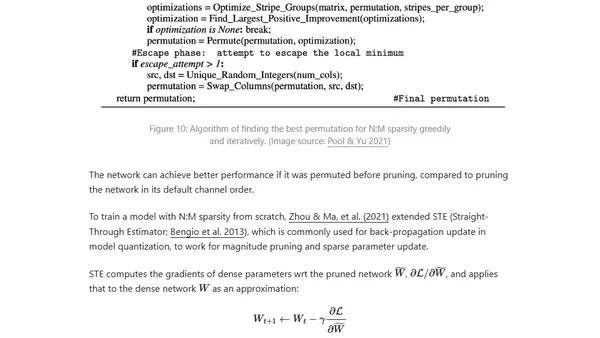
Explores techniques to optimize inference speed and memory usage for large transformer models, including distillation, pruning, and quantization.