Comparing HTML Minifiers
A comparison of HTML minifiers, discussing benchmarks, trade-offs in effectiveness, speed, and security, and the importance of informed tooling decisions.
Release of dns-benchmark-tool v0.3.2, a CLI tool for testing and comparing DNS server performance.
Explains how hardware performance depends on software selection and tuning, using a three-stage rocket analogy for tech leaders.
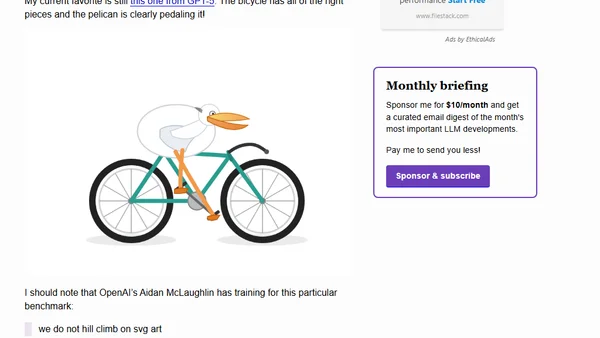
A humorous look at AI model benchmarking using the challenge of generating an SVG of a pelican riding a bicycle, and the risks of labs 'gaming' the test.
Announcing dns-benchmark-tool, an open-source Python package for testing and comparing DNS server speeds to optimize application performance.
Analyzes common flaws in C# ArrayPool benchmarks, explaining how JIT optimizations can invalidate results and how to fix them.
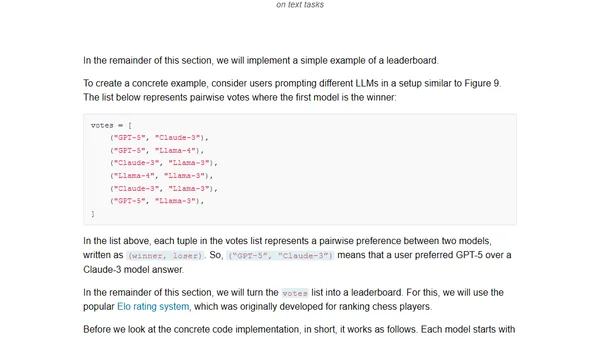
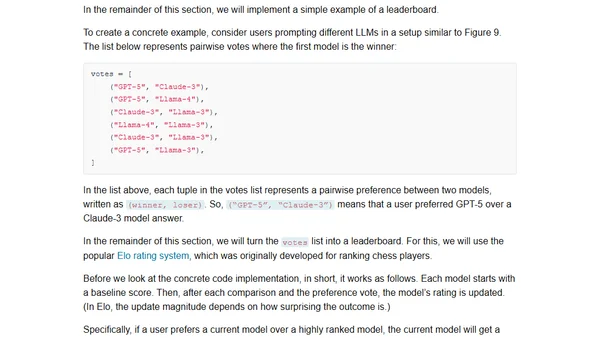
A guide to the four main methods for evaluating Large Language Models, including code examples and practical implementation details.
Explores four main methods for evaluating Large Language Models (LLMs), including code examples for implementing each approach from scratch.
A technical exploration of seven methods to intentionally waste CPU time for precise durations, focusing on user-land implementations for profiling tests.
A performance comparison of Visual Studio 2026 vs. 2022, focusing on build times and resource usage for a large .NET Framework solution.
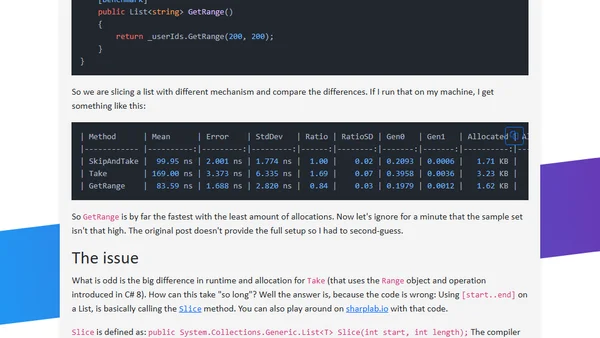
Analyzes C# performance benchmarks for slicing lists, comparing Skip/Take, Range operator, and GetRange methods, highlighting a common benchmarking error.
A developer benchmarks MicroPython performance on various microcontrollers, comparing them to a Raspberry Pi 4 and a laptop.
Explores challenges and methods for evaluating question-answering AI systems when processing long documents like technical manuals or novels.
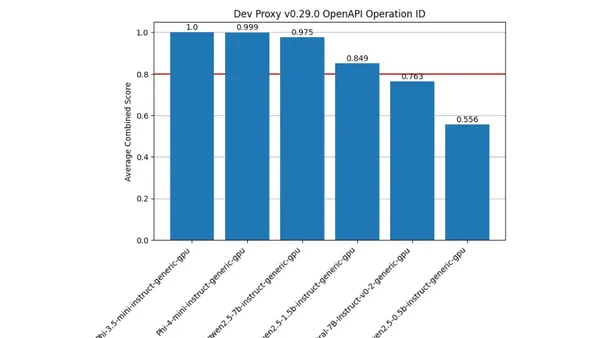
A guide to benchmarking language models using a Jupyter Notebook that supports any OpenAI-compatible API, including Ollama and Foundry Local.
Highlights key performance improvements in .NET 10, including stack allocation optimizations and delegate escape analysis, with benchmark comparisons.
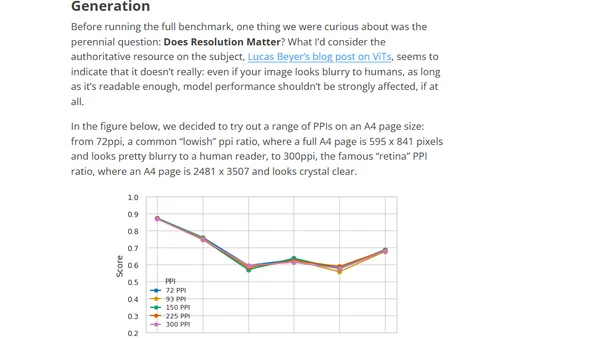
Introduces ReadBench, a benchmark for evaluating how well Vision-Language Models (VLMs) can read and extract information from images of text.
Explains why iterating over a concrete List<T> in C# is faster than iterating over an IList<T> interface, covering boxing and virtual method overhead.
Explores the concept of software benchmarks as falsifiable hypotheses for predicting real-world system performance, not just speed tests.
Explains the difference between Pass@k and Pass^k metrics for evaluating AI agent reliability, highlighting why consistency matters in production.
Analyzes a viral LinkedIn claim about IEnumerable vs IEnumerator performance in C#, debunking the 2x speed difference with a flawed benchmark.