Hexmaps for NZ District Health Boards
A technical tutorial on creating hexagon maps (hexmaps) for visualizing New Zealand District Health Board data using the R programming language and the DHBins package.
Thomas Lumley writes thoughtful, in-depth articles on statistics, data analysis, and statistical modeling. His blog explores topics like survey methods, regression, simulations, and inference with a rigorous yet reflective approach.
218 articles from this blog
A technical tutorial on creating hexagon maps (hexmaps) for visualizing New Zealand District Health Board data using the R programming language and the DHBins package.
A critique of the Oxford-Munich Code of Conduct for Data Scientists, focusing on its technical recommendations on sampling and data retention.
Explains why parentheses cause R code assignments to print their values, covering invisibility flags and the behavior of the `(` function.
Explains why the rimu R package avoids tidyverse for type safety with multiple-response data, using a custom S3 class approach.
Introducing the 'rimu' R package for manipulating and analyzing multiple-response data, with examples using ethnicity survey data.
A technical guide on extending the R survey package to support instrumental variable regression (ivreg) with complex survey data.
A technical note on calculating denominator degrees of freedom in survey-weighted generalized linear models (svyglm) for complex sample designs.
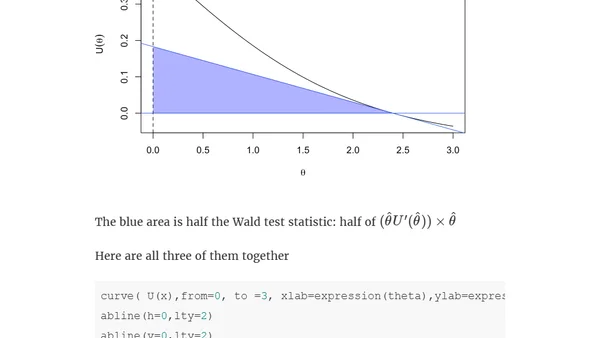
Explains the relationship between Wald, score, and likelihood ratio tests in statistical modeling using visual diagrams and R code examples.
A statistical re-analysis of a published study on the mouse microbiome and autism, examining data and p-values from behavioral experiments.
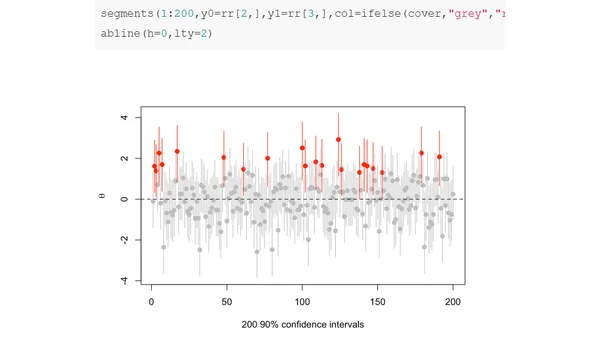
A statistical analysis discussing the limitations of confidence intervals, using examples from small-area sampling to illustrate their weak properties.
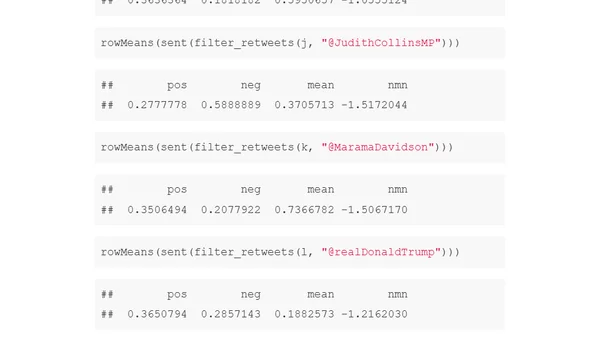
Analyzing tweet sentiment towards public figures using R, word embeddings, and logistic regression models to measure online negativity.
Explores statistical efficiency of estimators in nearly-true regression models under two-phase sampling, focusing on local asymptotic minimax theory.
A technical guide on handling 'plausible values' in survey data analysis using R, including code for the survey package.
Explores challenges in applying weighted penalized least squares to linear mixed models for survey data, highlighting estimation issues.
A technical analysis verifying a statistical calculation from an XKCD comic, involving normal distribution probabilities and R code.
A technical analysis of bus punctuality using Auckland Transport API data, with R code for data processing and visualization.
A comparison of warranty disclaimers in statistical software licenses, focusing on R, SAS, Stata, and SPSS, and their implications for users.
A critique of the Shapiro-Wilk normality test, arguing it's often misused due to the Central Limit Theorem and is rarely the scientifically relevant question.
Explores the challenge of machine learning models recognizing 'unknown' inputs, using mushroom classification as an example.
Explores optimal sampling design for logistic regression in case-control studies, analyzing Neyman allocation and two-phase sampling variances.