Batch vs. Streaming: Choose the Right Processing Model
A guide to choosing between batch and streaming data processing models based on actual freshness requirements and cost.
Alex Merced — Developer and technical writer sharing in-depth insights on data engineering, Apache Iceberg, data lakehouse architectures, Python tooling, and modern analytics platforms, with a strong focus on practical, hands-on learning.
610 articles from this blog
A guide to choosing between batch and streaming data processing models based on actual freshness requirements and cost.
Explains data partitioning and organization strategies to drastically improve query performance in analytical databases.
Explains the importance of automated testing for data pipelines, covering schema validation, data quality checks, and regression testing.
Explains the importance of pipeline observability for data health, covering metrics, logs, and lineage to detect issues beyond simple execution monitoring.
A practical, tool-agnostic checklist of essential best practices for designing, building, and maintaining reliable data engineering pipelines.
A comprehensive guide to data modeling, explaining its meaning, three abstraction levels, techniques, and importance for modern data systems.
Explains the three levels of data modeling (conceptual, logical, physical) and their importance in database design.
Compares Star Schema and Snowflake Schema data models, explaining their structures, trade-offs, and when to use each for optimal data warehousing.
Explores how data modeling principles adapt for modern lakehouse architectures using open formats like Apache Iceberg and the Medallion pattern.
Explains dimensional modeling for analytics, covering facts, dimensions, grains, and table design for query performance.
Explains Slowly Changing Dimensions (SCD) types 1-3 for managing data history in data warehouses, with practical examples.
Explains why transactional data models are inefficient for analytics and how to design denormalized, query-optimized models for better performance.
Explains database denormalization: when to flatten data for faster analytics queries and when to avoid it.
Explains Data Vault data modeling, its core components (Hubs, Links, Satellites), and the problems it solves for complex, evolving data sources.
Seven common data modeling mistakes that cause reporting errors and slow analytics, with practical solutions to avoid them.
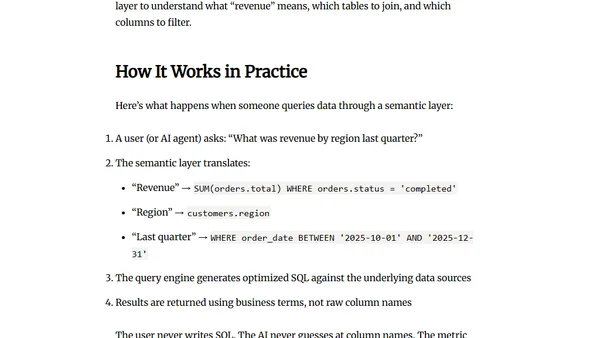
Explains what a semantic layer is, its components, and how it provides consistent business definitions for data queries and AI agents.
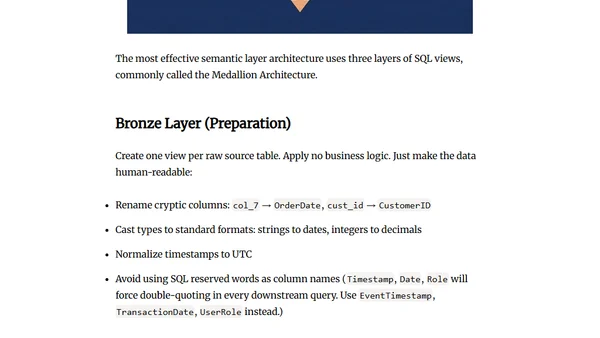
A step-by-step guide to building a robust semantic layer for consistent data metrics, covering architecture, stakeholder alignment, and implementation.
A comprehensive guide exploring the taxonomy, tools, and best practices for using AI-assisted coding tools in modern software development.
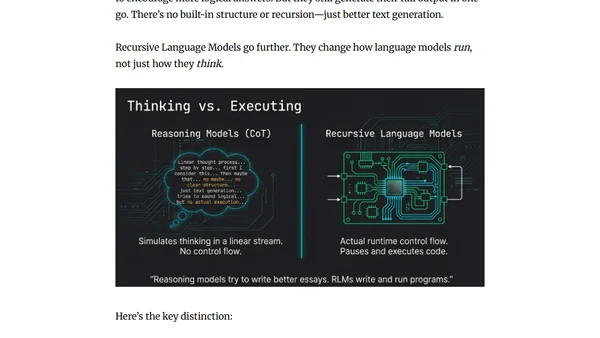
Explains Recursive Language Models (RLMs), which are LLMs that call themselves to break complex tasks into structured, reusable steps.
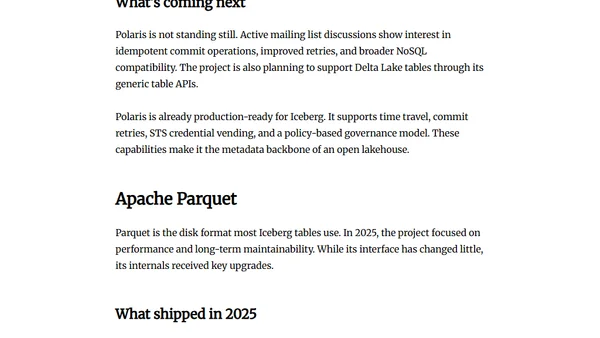
A 2025 year-in-review of key Apache data projects: Iceberg, Polaris, Parquet, and Arrow, detailing their major updates and future roadmap.