How well do agents use test/verification techniques?
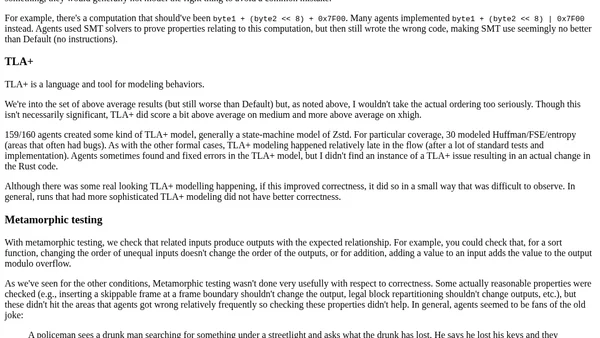
Testing how well AI coding agents use various test and verification techniques to improve software quality.
DanLuu.com is the personal blog of Dan Luu, known for long-form essays that mix systems thinking with careful measurement and clear writing. The topics range from computer latency and input lag, testing versus informal reasoning, and concurrency bugs, to industry pieces on developer compensation and curated lists of programming blogs worth reading. Many posts include data, historical context, and reproducible reasoning, which is why the site is often cited in courses and shared across the developer community. The design is intentionally minimal, which puts all attention on the ideas.
136 articles from this blog
Testing how well AI coding agents use various test and verification techniques to improve software quality.
I was curious how well the predictions of the most widely cited AI skeptic I've seen (Ed Zitron) have done, so I looked at how his predictions panned
I used to wonder why I see so many more bugs than most people. I easily observe hundreds to thousands of bugs per week and nothing seems to work, but
Explores how LLMs enable custom, high-performance software optimization, making slow code unnecessary.
Discusses how LLMs make it easy to game benchmarks, creating fake performance gains, and the need for careful auditing.
Explores whether dynamic languages are more token-efficient for LLM coding agents, critiquing existing evals and suggesting better benchmarking approaches.
Analysis of benchmarking exercises including napkin math performance estimates, DeepSWE, Senior SWE-Bench, and winter tire analogies.
A developer's reflections on using AI agents for coding, testing, and bug fixing, including a fabricated bug reproduction story.
The article argues that Steve Ballmer was an underrated CEO who made crucial long-term investments that set Microsoft up for its future success under Satya Nadella.
Analyzing if a Codenames bot can win using only card layout patterns, without understanding word meanings.
Analyzes public reactions to AI bias claims, contrasting them with responses to traditional software bugs, using a viral example.
Analysis of internal FTC memos reveals a flawed 2011-2012 Google antitrust investigation, citing a lack of tech industry understanding.
Analysis of how modern, bloated websites perform poorly on low-end devices, despite high-speed internet connections.
Explores how larger platforms often have worse fraud, spam, and support issues compared to smaller, more curated services.
An analysis of why achieving consensus on platform moderation rules is impossible, using a simple game about park vehicle rules as an example.
An analysis of the Quinn Emanuel report on Cruise's handling of a 2023 pedestrian accident involving an autonomous vehicle.
Analyzes why creators choose short-form social media over blogs, citing engagement, audience, ease, and monetization.
A comparison of search result quality across Google, Bing, and alternative engines, testing how well they handle generic queries.
A transcript of Elon Musk's controversial on-stage appearance with Dave Chappelle, correcting media reports about the crowd's reaction.
A cleaned-up, de-interleaved transcript of text message exhibits from the Twitter v. Elon Musk lawsuit, presented for clarity.