Volcano, Vectorized, Compiled: How Engines Execute Your Query
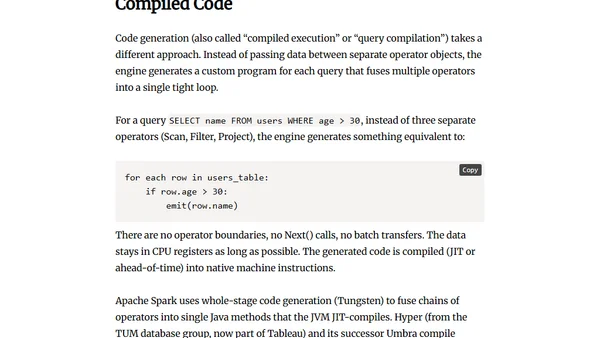
Explores query execution models: Volcano (row-at-a-time), vectorized (batch processing), and compiled code generation for CPU efficiency.
Alex Merced — Developer and technical writer sharing in-depth insights on data engineering, Apache Iceberg, data lakehouse architectures, Python tooling, and modern analytics platforms, with a strong focus on practical, hands-on learning.
610 articles from this blog
Explores query execution models: Volcano (row-at-a-time), vectorized (batch processing), and compiled code generation for CPU efficiency.
Explores data partitioning strategies like hash, range, and list partitioning for query engines, focusing on performance and data distribution.
Explores how database engines manage memory using buffer pools, caches, and page replacement policies to optimize query performance.
Explains distributed join strategies: shuffle, broadcast, and co-located joins, focusing on network costs in query engines.
Explains concurrency control in databases, covering 2PL, MVCC, isolation levels, and OCC for handling simultaneous reads/writes.
Explains the Apache Software Foundation's history, governance model, and its role in supporting open-source data lakehouse technologies.
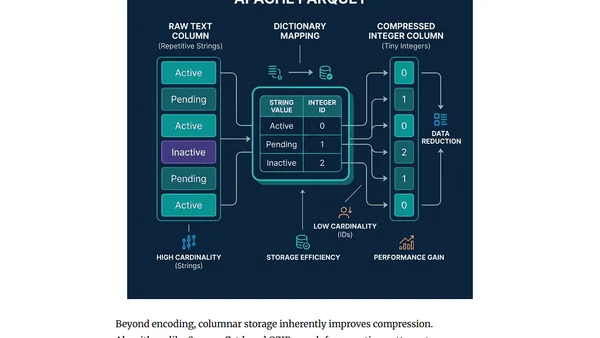
Explains Apache Parquet's columnar architecture, dictionary encoding, and performance benefits for data analytics.
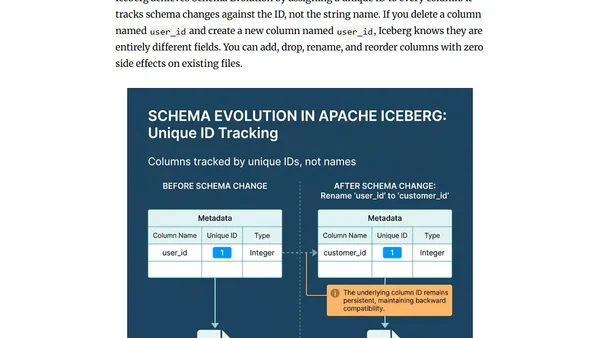
Explains Apache Iceberg, a table format that replaces directory-based metadata with file-level tracking for scalable analytics on cloud storage.
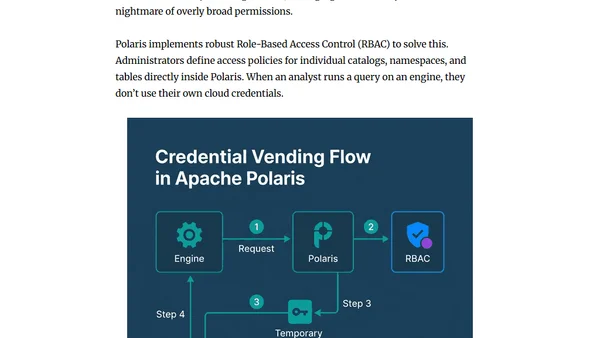
Apache Polaris is an open-source catalog service that unifies the Iceberg ecosystem by implementing the Iceberg REST API for vendor-neutral lakehouse metadata management.
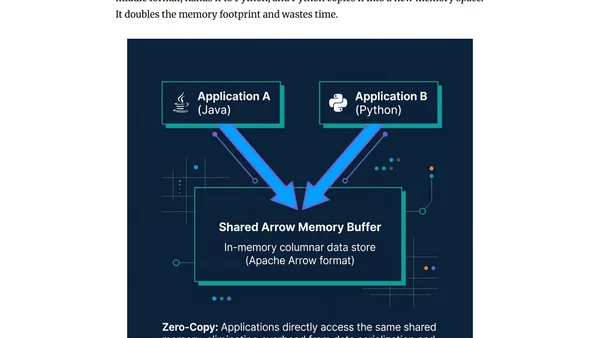
Explains how Apache Arrow eliminates the serialization tax by providing a standardized in-memory columnar format for fast data movement.
Explains the modular Apache Lakehouse architecture using open-source components like Parquet, Iceberg, Polaris, and Arrow for vendor-neutral data management.
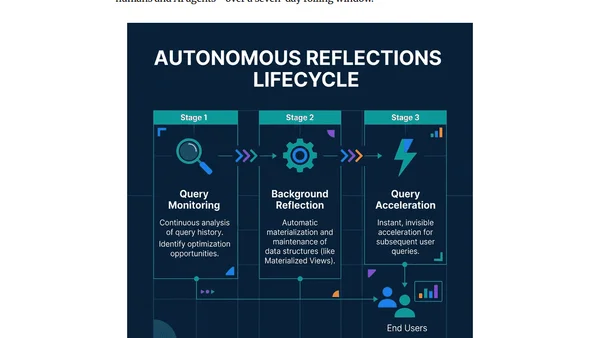
Explores how AI agents can safely perform analytics on Apache Lakehouse using semantic layers and autonomous reflections.
A comprehensive guide to managing context for OpenAI Codex across browser, CLI, and app interfaces for effective software development.
A guide to using Claude Desktop's advanced context management features: MCP servers, Computer Use, and local file access for technical workflows.
A guide to managing context and instructions for using Claude CoWork, an autonomous AI agent for knowledge workers handling files and tasks.
A comprehensive guide to context management strategies for developers using the Claude Code terminal-native coding assistant.
A guide to managing context and using Google's integrated AI tools, Gemini and NotebookLM, for effective knowledge work and research.
A guide to managing context in Gemini CLI, a terminal-native AI development tool, using files, memory, and MCP servers.
A guide to managing context in Google Antigravity, an agent-first IDE, focusing on Skills, Knowledge Items, and Artifacts for autonomous coding workflows.
A guide to context management strategies for OpenCode, an open-source terminal AI coding agent with a dual-agent architecture.