Sparse correlation and the Central Limit Theorem
Explores sparse correlation structures in statistical models and the conditions under which the Central Limit Theorem holds for dependent data.
Thomas Lumley writes thoughtful, in-depth articles on statistics, data analysis, and statistical modeling. His blog explores topics like survey methods, regression, simulations, and inference with a rigorous yet reflective approach.
218 articles from this blog
Explores sparse correlation structures in statistical models and the conditions under which the Central Limit Theorem holds for dependent data.
Announcing a preprint for the svylme package, introducing the svy2lme function for fitting linear mixed models to complex survey data.
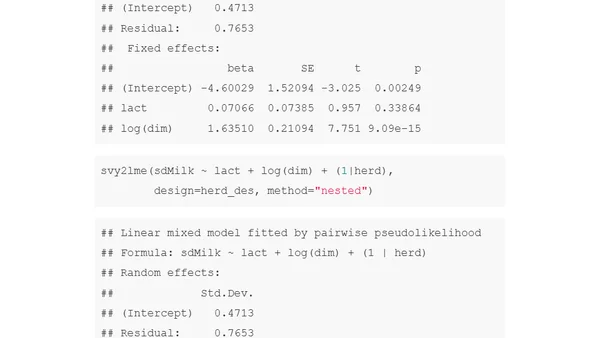
A technical tutorial on fitting linear mixed models using pairwise pseudolikelihood in R with the svylme package, using educational survey data.
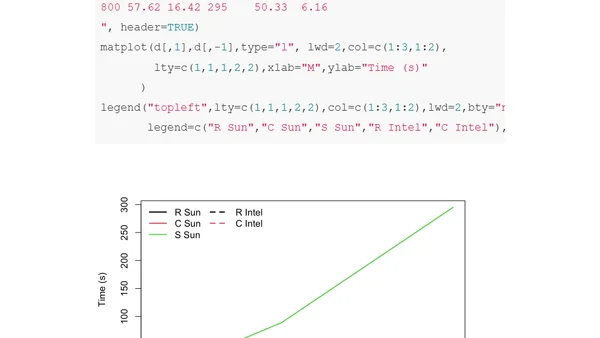
Analyzing a 1990s benchmark comparing R, S, and C performance, and revisiting it on modern hardware to discuss speed improvements and limitations.
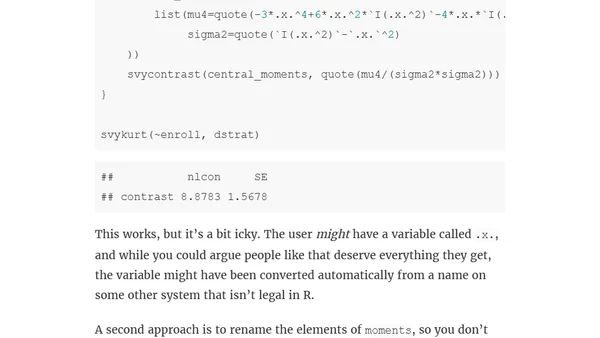
A technical guide on computing kurtosis and its standard error using R's survey package, including function creation and delta method application.
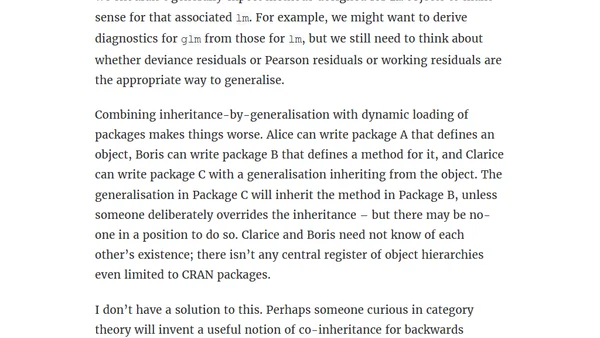
Discusses the conceptual problem of inheritance in object-oriented programming for statistical methods, using R's lm and glm classes as examples.
A technical exploration of using pairwise likelihood in linear mixed models with complex sampling, comparing results from svylme and lme4 packages.
Explores the challenges of applying signed rank tests to complex survey data and proposes a design-independent rank transformation method.
Explores the concept of class imbalance in machine learning, drawing parallels to medical training and questioning if it's a problem or an inherent feature.
A technical discussion on the 'fourth-root' condition for estimator consistency in statistical models like GEE, exploring asymptotic theory and nuisance parameters.
A mathematical proof showing the determinant of a correlation matrix is at most 1, using eigenvalues and the AM-GM inequality.
Analyzing the 'sandwich' package's behavior with aggregated count data in Poisson regression, comparing standard errors between individual and aggregate models.
A statistical analysis article examining the Wilcoxon and Kruskal-Wallis rank tests, clarifying they compare population mean ranks, not medians.
Explains the proportional odds model for ordinal data, its assumptions, and discusses methods for testing the proportionality of odds.
Explores the intersection of multiple imputation and probabilistic record linkage, proposing a method to sample link sets for robust statistical analysis.
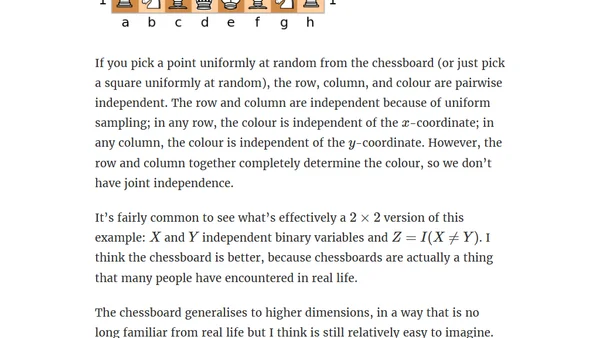
Explains why pairwise independence of variables does not imply joint independence, using a chessboard as an intuitive counterexample.
Explores the connection between the Welch-Satterthwaite t-test and linear regression using the sandwich variance estimator.
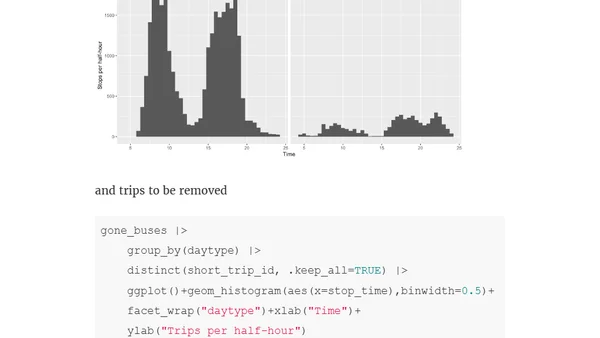
Analysis of Auckland bus cancellations using R and GTFS data to visualize which trips are being removed from the timetable.
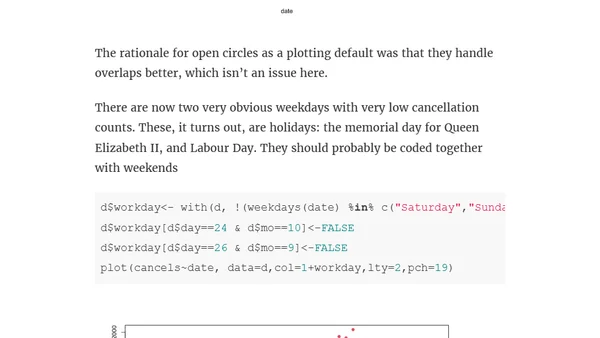
A technical walkthrough of visualizing and improving a graph of Auckland bus cancellation data using R, focusing on data representation and coding techniques.
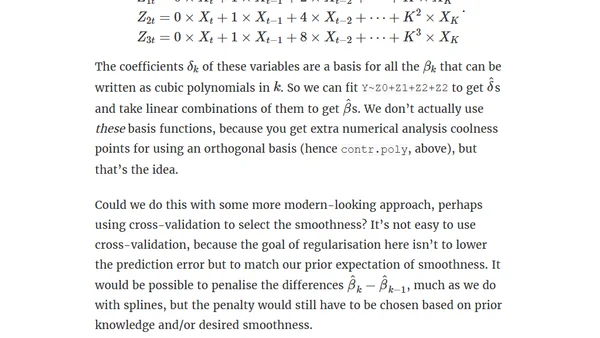
A technical article explaining polynomial distributed lag models for regularization in time-series analysis, including code archaeology and R implementation.