The Double-Slit Experiment and AI: Why Context Changes the Answer
Explores how the double-slit experiment offers a mental model for evaluating AI behavior under different conditions, not quantum AI.
Build an offline Python grader for AI agents that separates control, behavior, and outcomes—not just explanations.
AI reward design: define business outcomes, not easy metrics. Separate permissions, verification, escalation, and efficiency to avoid gaming.
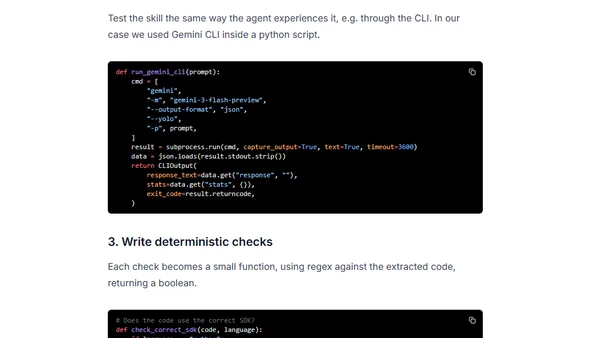
A guide to systematically evaluating and testing AI agent skills, covering success criteria, building an evaluation harness, and improving skill performance.
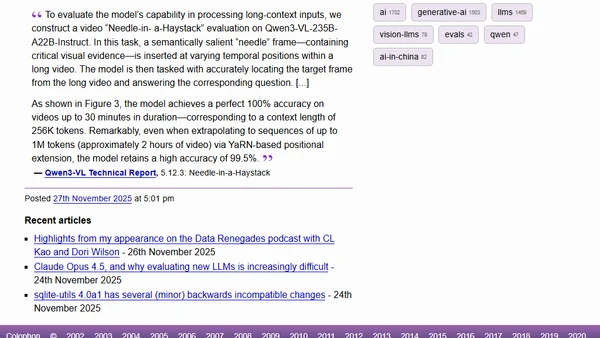
Technical report on Qwen3-VL's video processing capabilities, achieving near-perfect accuracy in long-context needle-in-a-haystack evaluations.
Argues that reading raw AI input/output data is essential for developing true intuition about system behavior, beyond just metrics.
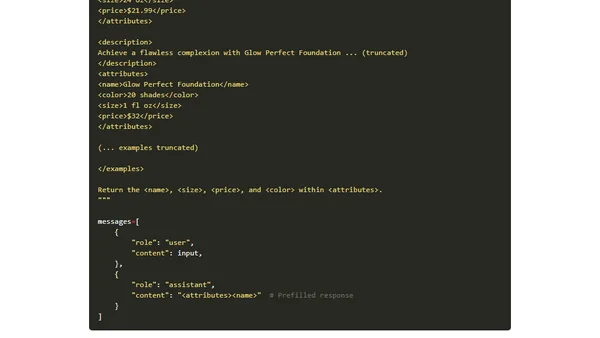
Explains core prompting fundamentals for effective LLM use, including mental models, role assignment, and practical workflow with examples.
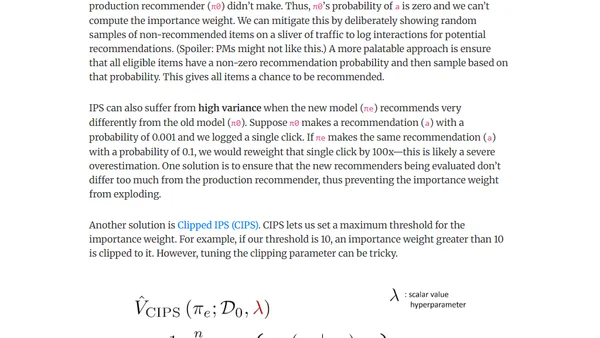
Explores counterfactual evaluation as an alternative to A/B testing for offline assessment of recommendation systems.